The Ralph Wiggum Loop, evolved
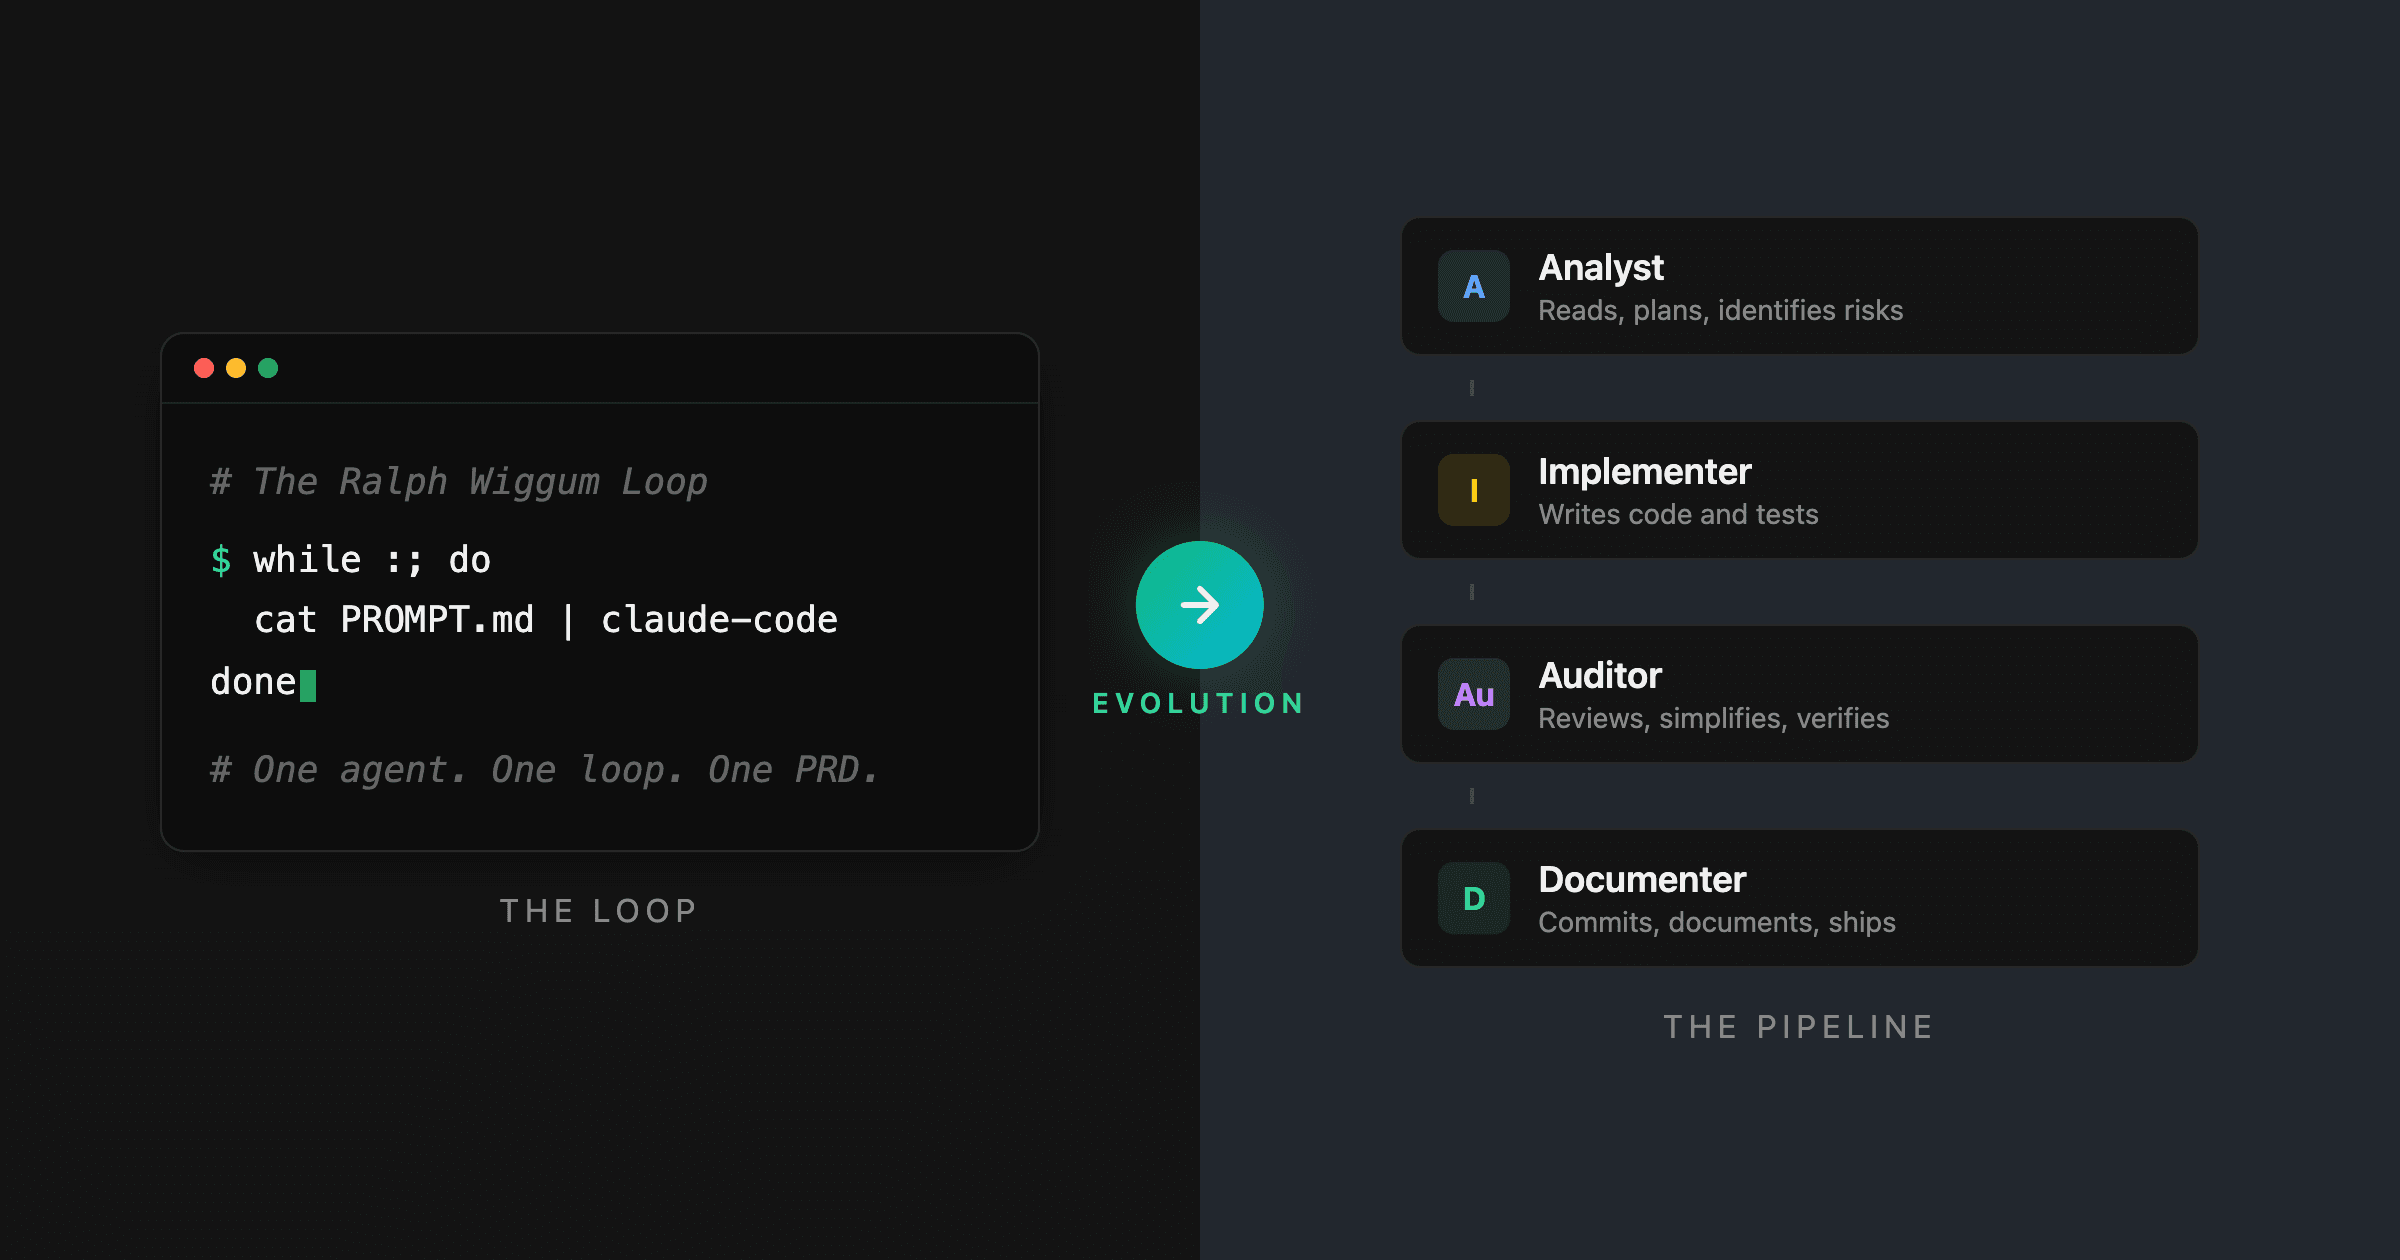
In mid-2025, Geoffrey Huntley published something that changed how developers think about AI coding. He called it the Ralph Wiggum Loop — a beautifully simple idea:
while :; do cat PROMPT.md | claude-code ; doneFeed a PRD to Claude Code in an infinite bash loop. Each iteration, the agent reads the current codebase, picks up where the last run left off, implements one task, commits, and loops back. Fresh context every time. No hallucination drift. Just persistent, autonomous code generation.
It worked. Huntley built CURSED — a full programming language — using nothing but the loop. Others followed. At a Y Combinator hackathon, teams shipped six repositories overnight for $297 in API costs — work estimated at $50K in contractor time. The technique spawned dozens of open-source tools: ralphy, ralph-orchestrator, open-ralph-wiggum, smart-ralph. The community exploded.
The Ralph Wiggum Loop proved something fundamental: AI agents can autonomously ship real, production code from a specification. That was the breakthrough.
But it only answered one question.
I hit the wall building something hard
I didn't set out to build a dev tool. I set out to build something genuinely hard — a Bitcoin-anchored coordination protocol I'd been designing called BAP. Bonded nodes, a typed event machine, deterministic state transitions, treasury signing, the works. The kind of system where one wrong sequencing decision quietly cascades through everything downstream. And I wanted to build it with AI, alongside a friend.
So I ran it as a Ralph loop. For isolated tasks, it was magic.
Then the thing that broke first wasn't the code. It was the plan.
A system like that is almost entirely interdependence — this can't start until that's anchored, this event type depends on that one resolving first. The loop reads a frozen PROMPT.md and runs. But where does the living plan live? How do you change it when you learn something on story 12 without throwing away everything and starting over? How do you steer it when the agent wanders off into a corner you didn't mean? I was hand-editing a giant markdown file and praying — I had quietly become the single point of failure for the entire plan.
And I wasn't doing it alone. Two of us, one prompt file, and no real way to plan or steer the thing together. The loop is a single-player machine.
Then the rest piled on. Who reviews this before it ships? When I had several plans going, which parts belonged in the next release? How do I run five things at once without them colliding in the same files? How would I ever know if the agents were actually getting better?
The loop never claimed to answer any of that. It's a proof of concept — and a great one. But I needed a system. So I built Trinity. Here are the evolutions that took it from a bash loop to a collaborative release pipeline.
1. From a frozen prompt to a living plan you can steer
The loop thinks in one frozen PROMPT.md. Trinity thinks in a living plan you talk to.
Planning happens through Architect — a conversation, not a form. Describe what you want to build and it drafts a full PRD: phases, epics, stories, and a real dependency graph. Under the hood a five-phase planning pipeline does the work — Architect designs the structure, a Story Writer fills in the stories, a Dependency Mapper wires them together and drops in quality checkpoints, a Target Mapper assigns each story to the right part of your codebase, and a Calibrator authors each story's execution settings (which model tier, how much review, how much effort).
But here's the part I didn't have on that markdown file: you steer it in plain language. Describe a change — "add user profiles," "split this monolith," "drop the quarterly reports epic" — and Architect reshapes the work atomically, respecting whatever stories are already running. The plan stops being a document you nervously hand-edit and becomes an object you talk to.
And you choose what actually ships. PRDs roll into releases — you decide which plan iterations go into each one. Trinity validates the dependency graph, then the release runs its own pipeline (preflight, review, release notes, a human gate) and manages the lifecycle from created to released. Per-repo semver, graded automatically from what each repo changed. Automatic changelogs. Optional release-branch isolation.
Shipping code was never the hard part. Holding the plan — and steering it as you learn — is.
2. Collaboration wasn't a feature we added. It was the point.
The second thing the loop couldn't do was let two people build together. So that was never bolted on — from line one, Trinity was designed around a team of humans and agents, planning the work and running the loops together.
Every planning conversation is shared and real-time. Your teammates see the same plan forming, the same agent thinking, the same decisions getting made — live. Need the agent on your machine instead? @mention it and the session hands off in under a second, running under your credentials, your keys, your environment. In a group it stays quiet until it's tagged; when you're solo it just answers.
And it scales down as cleanly as it scales up. Even working alone, you're already building with a team — your agents plan, build, review, and remember alongside you. Bring real people in whenever you want, and the exact same loop just gets more hands on it.
The loop is single-player. Building real software rarely is.
3. Multi-agent review, not single-agent looping
In the Ralph Loop, one agent does everything: read the spec, write the code, run the tests, commit. If it makes a mistake, the next loop iteration might catch it. Or it might not.
Trinity doesn't have one pipeline — it has three, each designed for a different job:
- Story pipeline — the workhorse. Four agents (Analyst → Implementer → Auditor → Documenter) take a single story from spec to shipped PR.
- Checkpoint pipeline — quality gates mid-release. Analyst → Audit/Fix loop → Documenter → Human Gate. Catches codebase-wide issues before they compound.
- Release pipeline — the final pass before a version ships. Analyst → Audit/Fix loop → SEO Audit → Documenter → Human Gate. Includes an SEO audit for web targets.
Analyst
Reads the story requirements, analyzes the codebase for context, and creates a detailed implementation plan. Identifies risks, dependencies, and required services. Read-only — no code changes.
Implementer
Executes the Analyst's plan. Writes code across files, runs tests and fixes failures, handles Docker services. Does not commit.
Auditor
Runs 1–7 simplification passes scaled by story difficulty and surface area. Full code review, build verification, and early exit on clean code.
Documenter
Writes the docs of every package the story touched into the repo, checks them against the documentation standard, and commits them with the code.
The Auditor alone changes everything. It's a dedicated review agent that sees the code fresh — no sunk cost, no attachment to what the Implementer wrote. That's what catches the bugs single-shot generation misses. And that same principle — specialized agents with specific jobs — carries through to the checkpoint and release pipelines, where audit/fix loops run until the codebase meets the bar.
4. Human oversight that's typed — and recoverable
The Ralph Loop runs unsupervised. That's the feature — and the risk.
Trinity gives you around twenty deterministic execution gates that pause the pipeline for human judgment. Not vague "approval" steps — specific, typed checkpoints, each carrying exactly what triggered it:
- Deviation approval when the Analyst wants to swap your specified tech stack for a concrete reason
- Missing secret when a story needs an API key — entered inline, encrypted, then the run resumes
- PR review after implementation, with the real branch-vs-base diff rendered right there in the gate
- Quality checkpoint before downstream work builds on an audited milestone
- Merge conflict when a PR can't merge cleanly and needs your call
- Story failed / blocked when an agent genuinely can't make progress
And here's the part that took the fear out of autonomy: gates are recoverable. A story never dead-ends. It parks with its completed work safe on disk, files a failure dossier, and Architect immediately drafts a way forward — retry, reshape, or delete — so by the time you look, a reviewable option is usually already waiting. Better still, instead of a binary approve/skip, you can just give feedback in plain language and the story re-enters the pipeline with it. Iterate on the agent's work without ever editing code yourself.
| Ralph Loop | Trinity | |
|---|---|---|
| Supervision | Runs unsupervised | Autopilot or manual, with configurable gates |
| Scope | All or nothing | Per-story configuration |
| Failure | Loop hangs or drifts | Parks, files a dossier, drafts a fix |
| Iteration | Re-edit the prompt, rerun | Give feedback in plain language, it re-enters the pipeline |
Full pipeline runs end-to-end without intervention. Analyze, implement, audit, document, PR, merge.
Pipeline pauses at gates for your approval. Toggle per-story: auto-clarify, auto-merge, auto-approve checkpoints.
You decide the balance. Auth system rewrite? Gate everything. Docs update? Let it fly. Same project, same pipeline, different levels of trust for different stories.
5. True parallel execution
The Ralph Loop is sequential by nature. One agent, one loop, one task at a time.
Trinity runs up to five workers in parallel, each executing a different story in its own isolated git worktree. A coordinator manages the job queue per release, with atomic job claims and dependency-aware scheduling. Stories only become runnable when their dependencies are satisfied.
Conflicts happen — that's unavoidable when multiple agents touch the same codebase. Trinity handles them with a dedicated resolver agent that understands the full context of both branches. It merges intelligently, not mechanically. No manual resolution, no broken builds.
Multi-repo workspaces
A single story can span multiple repositories with coordinated branching, across GitHub, GitLab, Bitbucket, and Forgejo alike. Branch names are derived from configurable templates at runtime — not stored — so the system stays flexible. Each repo tracks its own version independently.
Parallel Execution — 5 Workers, 5 Worktrees, AI-Powered Conflict Resolution
1:1.2.1 — Auth flow
1:1.2.2 — API routes
1:3.1.1 — Dashboard UI
1:2.1.1 — Billing
1:2.1.2 — Webhooks
5 stories · 5 branches · 5 worktrees · conflicts auto-resolved
Five stories. Five branches. Five worktrees. Conflicts auto-resolved.
6. History that compounds
The Ralph Loop's most elegant constraint is also its biggest limitation: fresh context every iteration. No memory of previous runs. Each loop starts from zero, reading the codebase to figure out what happened before.
Trinity keeps the history instead. Every agent hands off a structured report — the Analyst's plan, the Implementer's journal, the Auditor's verdict — and every one is stored, queryable, and read by the agents that come next. Each new PRD is planned against everything before it: every story that shipped, every attempt that failed and why.
Run 1: a story fails on a library pattern that breaks hydration, and its handoff records why. Run 2: the next PRD is planned with that failure and its reason in view, and the Implementer takes a different approach. Run 47: the project's history is deep — every decision, every failure, every recap — and the metrics dashboard shows it working, first-pass rate climbing and cost-per-merged-story falling.
The loop starts from scratch. The pipeline gets smarter.
We're just getting started
Everything above — a steerable plan, real collaboration, multi-agent review, recoverable gates, parallel workers, compounding history — is the core of Trinity. It doesn't begin to scratch the surface.
We haven't really talked about workspace collaboration beyond planning — shared projects, coordinated execution, role-based access, per-member spend. Or the code viewer built for the agentic era, where you can read a branch while an agent is working on it, with identity-aware blame. Or recaps and reports that summarize what shipped, what's blocked, and what it cost — generated automatically, no status updates by hand. Or configurable AI model tiers across seven providers — including local models via Ollama — so you bring your own keys and pay providers directly.
And the next room we're building on the exact same foundation: end-to-end-encrypted team chat, with your agents right there in the room. Because the collaboration substrate was the point from line one — chat is just the natural next surface for it.
The pipeline is the engine. But Trinity is the whole car.
From loop to pipeline
The Ralph Wiggum Loop deserves its place in the history of AI-assisted development. It proved the concept. It showed that AI agents, given a clear spec and persistent access to the codebase, can ship real software autonomously.
Trinity is what happens when you actually try to build something hard with that proof — and ask: now how do two people run a real software project this way?
The loop proved AI can build from a PRD. Trinity proves a team can ship releases.
A living plan you steer in plain language instead of a frozen prompt. Collaboration as the backbone instead of a single-player loop. Three specialized pipelines instead of one generalist. Around twenty typed, recoverable gates instead of unsupervised execution. Parallel workers with AI-powered conflict resolution instead of sequential tasks. Compounding history instead of amnesia.
From loop to pipeline. From frozen prompt to living plan. From proof of concept to production system.
Ready to evolve past the loop? Download Trinity — available for macOS and Linux.